arXiv · 2026

PredErase

Training-Free Object-and-Effect Removal with Predictive Latent Guidance

Waikit Xiu · Qiang Lu · Junbiao Chen · Xiying Li
The University of Hong Kong · Sun Yat-sen University

PaperCode

Overview

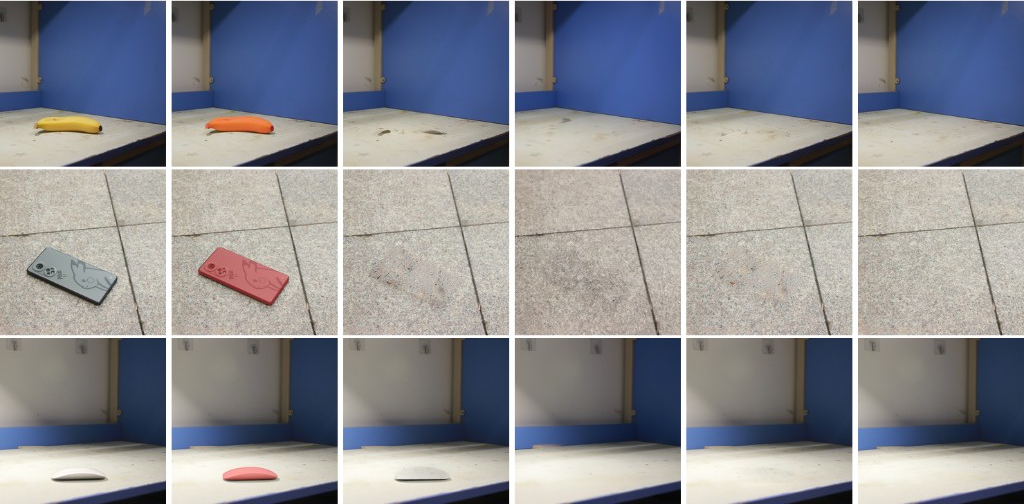
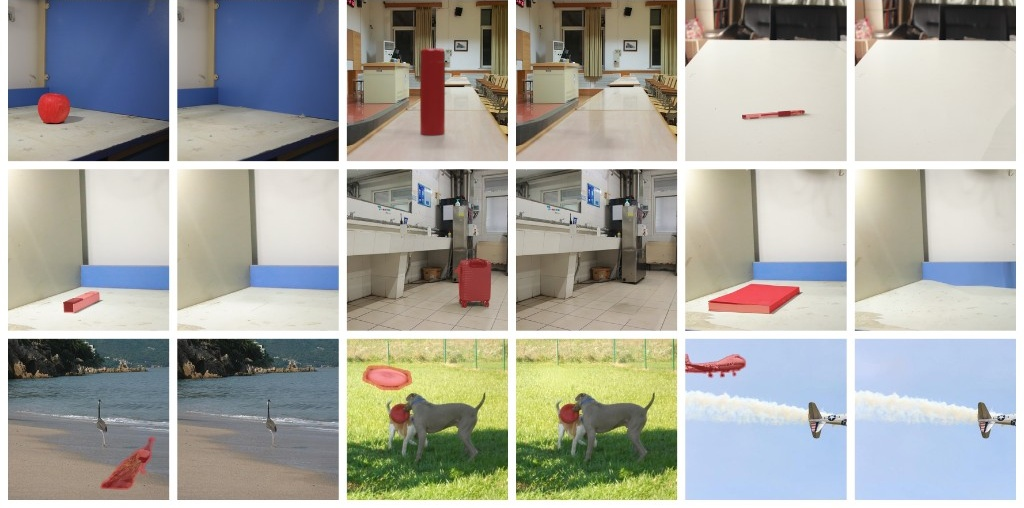
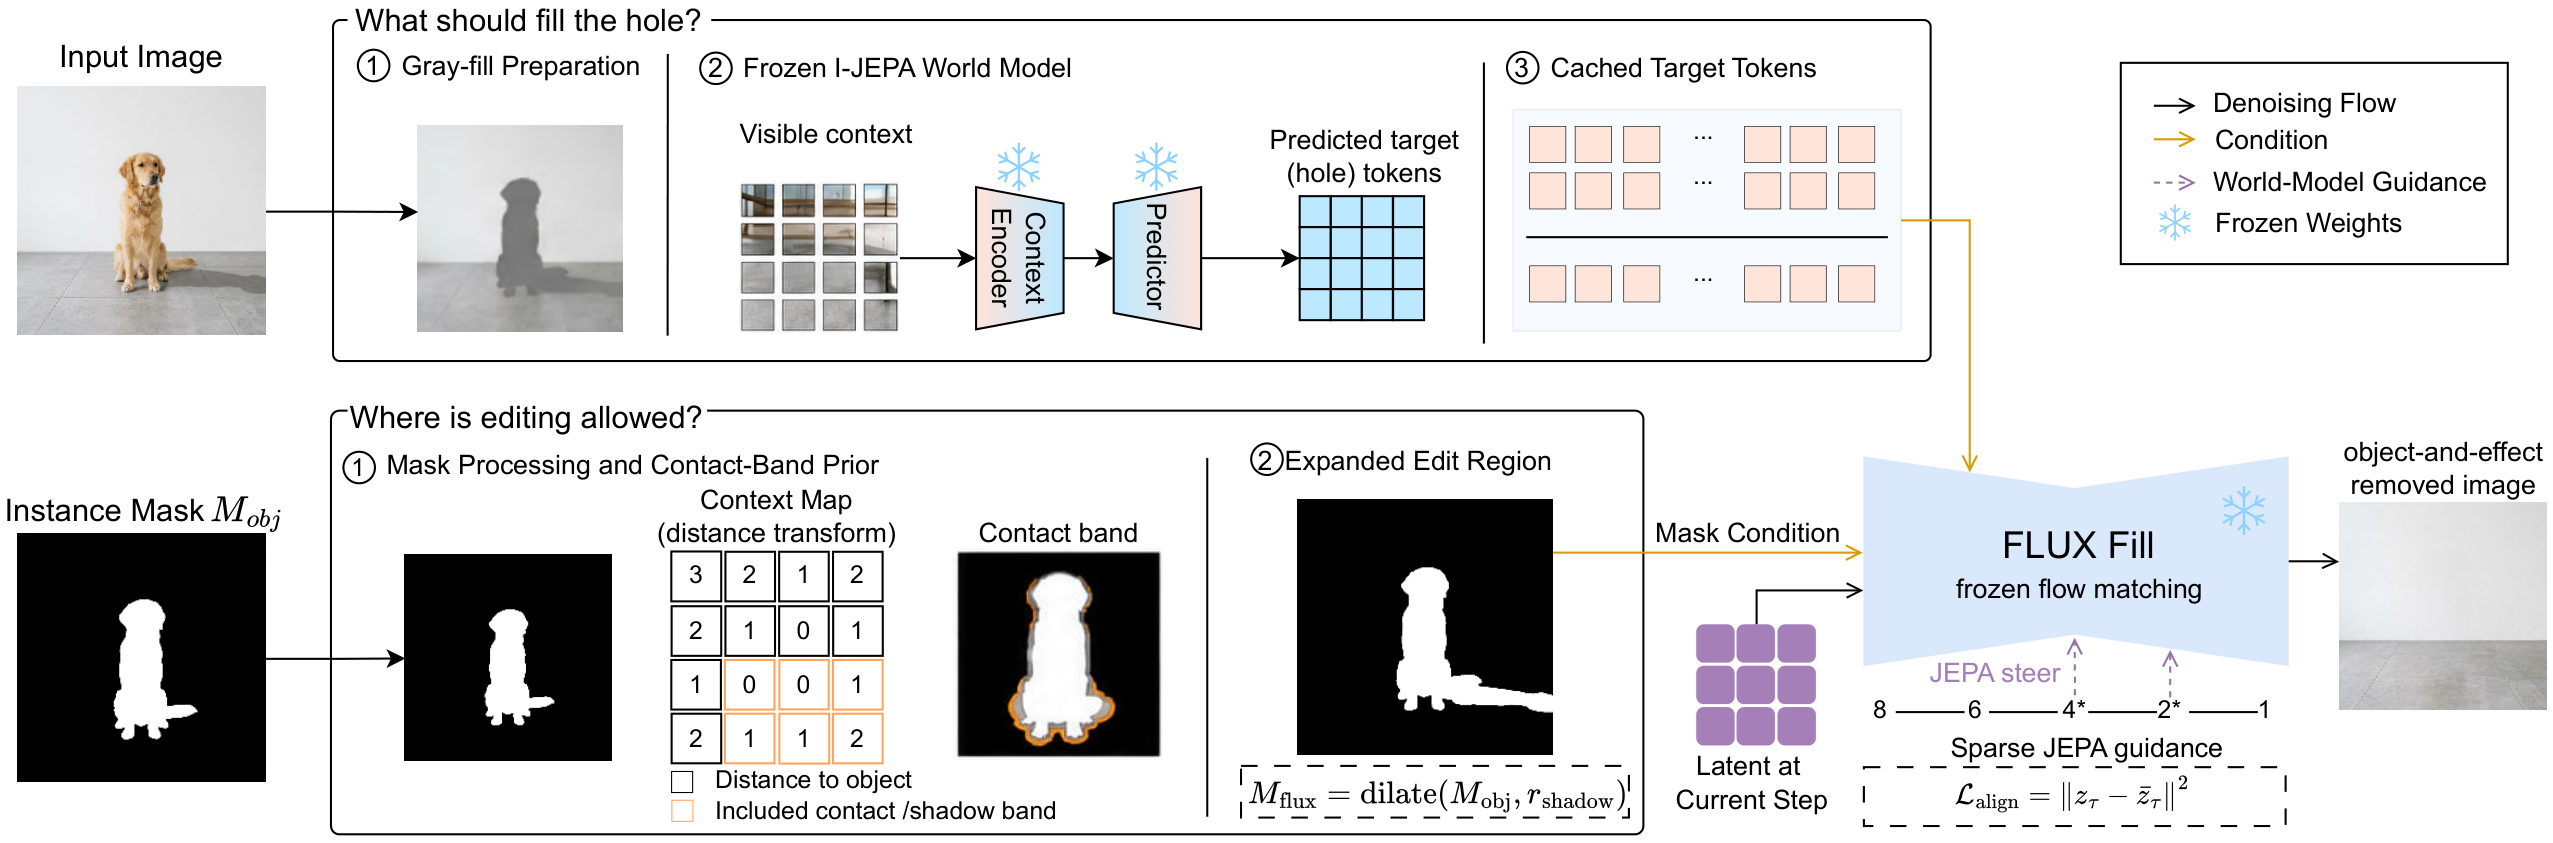
Removing an object is not simply filling a hole: cast shadows and contact shading remain. PredErase removes both the instance and its visual effects without paired training or model finetuning. FLUX.2-klein-4B and I-JEPA remain frozen; only test-time latent guidance is applied.

Where to edit

A contact-aware geometric prior expands an instance mask into an effect-aware editable support.

What to reconstruct

Cached I-JEPA hole predictions provide a semantic target for sparse projected updates.

What to preserve

Packed-latent locking fixes coordinates outside the support to protect the rest of the scene.

Predictive latent guidance
Evaluation

PredErase is evaluated on RemovalBench, RORD-Val, and DEFACTO-Val under OmniEraser and SmartEraser protocols. The qualitative comparison below uses instance-only masks and contrasts native FLUX.2, OmniEraser, PredErase, and clean plates.

Quick start

git clone https://github.com/xiuwk0820/PredErase.git; pip install -r requirements.txt; python scripts/run_inference.py --config configs/default.yaml --image examples/demo_image.jpg --mask examples/demo_mask.png --output outputs/demo.png

Citation

@article{xiu2026prederase, title={PredErase: Training-Free Object-and-Effect Removal with Predictive Latent Guidance}, author={Xiu, Waikit and Lu, Qiang and Chen, Junbiao and Li, Xiying}, journal={arXiv preprint arXiv:2609.00956}, year={2026}, url={https://arxiv.org/abs/2609.00956}}